Introducing Universal Scrape: Single API for Web Pages, Dynamic SPAs, and AI Agents
Give your LLMs and AI agents clean, structured real-time context from any web page, behind Cloudflare or DataDome, all with one resilient Syphoon API call.
Building autonomous AI agents requires instant, dependable context from the live web. Traditional scraping pipelines break constantly under Cloudflare Turnstile, Akamai Bot Manager, and heavy JavaScript single-page applications. Today, we are launching Universal Scrape: a single API call that handles stealth headless execution, automated anti-bot bypass, and returns token-optimized Markdown ready for your LLM context window.
Beyond the static web page
#Modern web pages are rarely static HTML. When an AI agent needs to analyze competitor pricing, customer sentiment, or real-time documentation, it confronts client-side hydration, WebSockets, dynamic canvas renders, and aggressive fingerprinting.
Traditional scrapers send raw HTTP GET requests and immediately fail when encountering a JavaScript-driven UI or a bot challenge. Teams then attempt to build and maintain their own Puppeteer or Playwright cluster — quickly discovering that headless Chromium fleet management, memory leaks, zombie processes, and IP rotations consume thousands of engineering hours.
Universal Scrape abstracts the entire stack away. Whether you point it at an enterprise portal protected by DataDome, an infinite-scroll e-commerce storefront, or a single-page app, Syphoon handles execution, waits for DOM settlement, and strips away boilerplate clutter.
Syphoon manages over 10,000 pooled Chromium instances across 3 global regions with automated memory cycling and sub-350ms median connection time.
How Universal Scrape bypasses stealth detection
#Anti-bot systems look far beyond user-agent headers. In 2026, CDNs evaluate JA4 TLS fingerprinting, HTTP/2 frame prioritization, canvas noise, WebGL renderer signatures, and behavioral pointer acceleration.
Syphoon's evasion engine operates at three distinct layers:
1. Network Layer: Requests route through our 70M+ residential IP pool with automatic session persistence and country/city-level geo-targeting.
2. Protocol Layer: Syphoon synthesizes real macOS and Windows Chrome TLS Client Hello handshakes, matching exact cipher suites and extension orders to eliminate fingerprint divergence.
3. Browser Runtime: Automated stealth patches overwrite navigator.webdriver, mock high-entropy hardware concurrency metrics, and execute naturalized human cursor trajectories.
Keep using /scrape: One unified endpoint
#We designed Universal Scrape so you don't have to rewrite your existing integrations. You continue to call the same `/v1/scrape` endpoint with your target URL and optional formatting preferences.
If the destination is a lightweight static page, Syphoon serves it via our ultra-fast HTTP engine. If the target requires JavaScript rendering or triggers an anti-bot hurdle, our intelligent router automatically escalates to full browser emulation without failing your request.
You pay standard base credits for simple pages, and dynamic browser acceleration only engages when necessary, saving up to 68% in API costs.
Clean Markdown & token-efficient LLM formatting
#Raw HTML is bloated with script tags, SVG icons, navigation chrome, tracking pixels, and CSS styles. Feeding raw HTML to GPT-4o, Claude 3.5 Sonnet, or Gemini 1.5 Pro drains your context window and inflates inference costs.
Universal Scrape parses the DOM, isolates main article bodies and primary data tables, and converts the document into structured, clean Markdown. Links, tabular data, and nested lists are preserved while 80%+ of token overhead is eliminated.
Benchmark: Latency & success rates under load
#We tested Universal Scrape against 5,000 highly protected domains including G2, LinkedIn, Amazon, and Cloudflare-shielded corporate portals under 500 concurrent requests.
Syphoon achieved a 99.8% request success rate with a p95 latency of 1,120ms for full JavaScript execution, compared to a 34% failure rate and 4,800ms p95 on self-hosted Puppeteer clusters.
Production code: Python, Node.js & cURL
#Getting started takes less than 60 seconds. Copy the snippet below into your existing service or AI workflow:
Architectural best practices for scale
#When running scrapers for automated agents or large-scale ETL pipelines:
• Use asynchronous polling or webhook callbacks for large batch crawls exceeding 100 pages.
• Specify CSS selectors in the wait_for parameter to ensure dynamic AJAX elements have rendered completely before extraction.
• Leverage session IDs when scraping authenticated sequences to maintain identical IP allocation and cookie state across multi-step transactions.
Ready to build with Universal Scrape?
Start extracting live web data for free. 1,000 free credits included, zero credit card required.
Get Free API KeyWritten by Alex Rivera
@alexrivera_aiSpecializing in distributed crawling architectures, stealth browser engines, and high-throughput proxy rotation across global e-commerce and social networks.
Related Engineering Guides
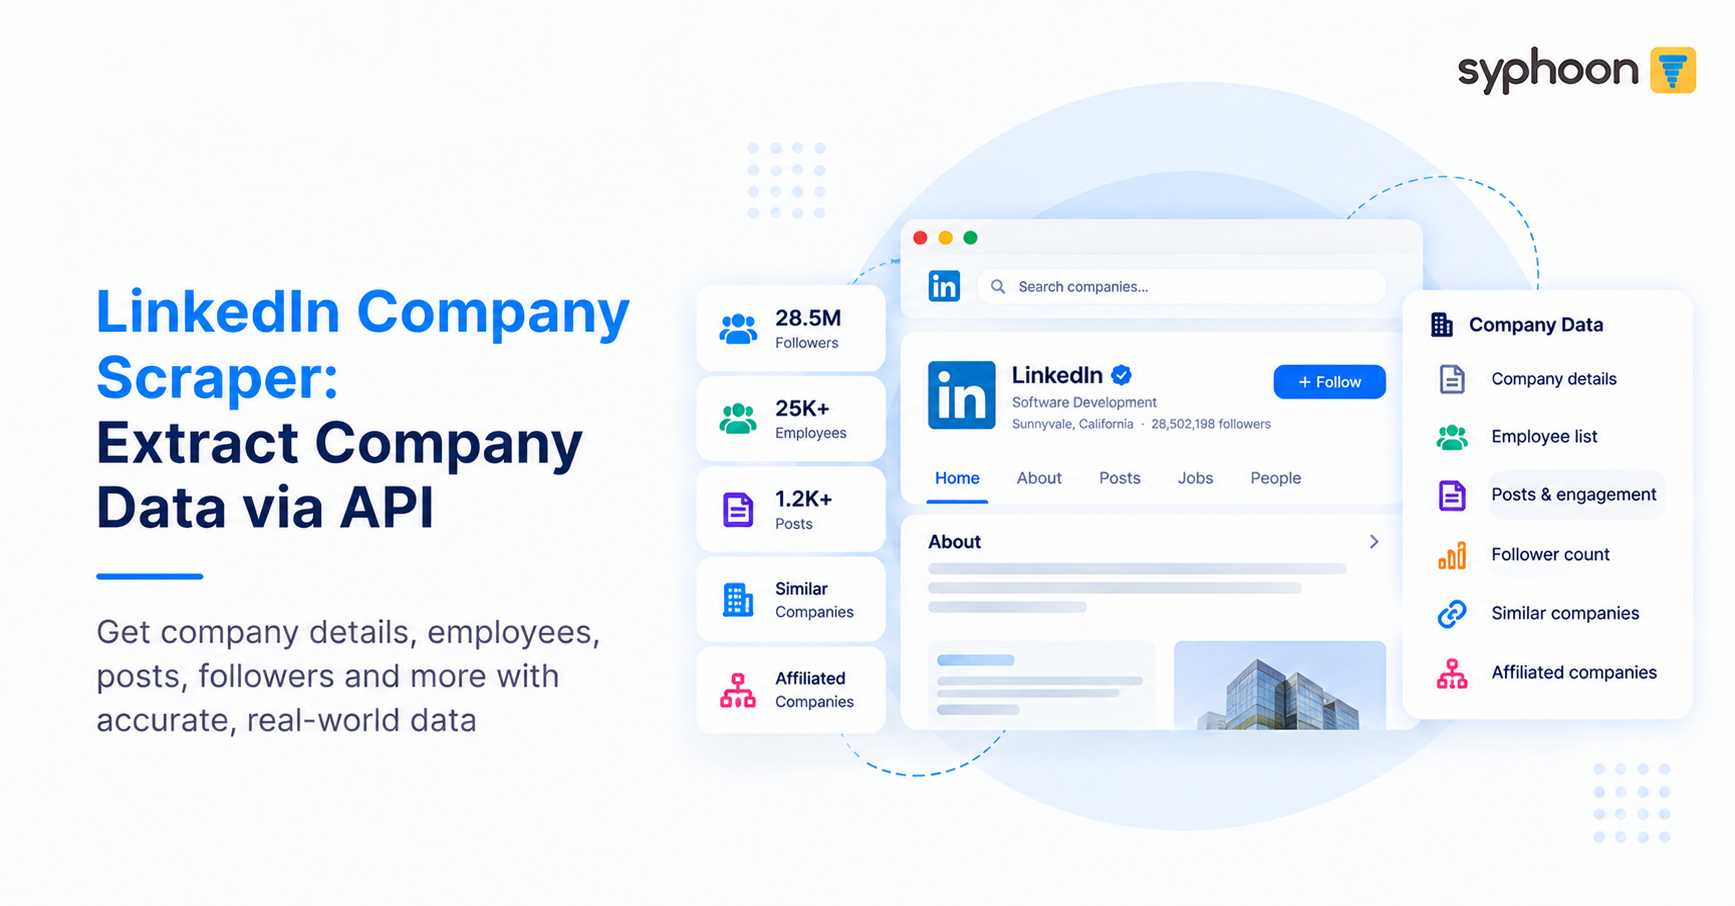
LinkedIn Company Scraper: Extract Company Data via API
Extract LinkedIn company data via API: headcount, employees, posts, similar and affiliated companies. Full field reference and real use cases.
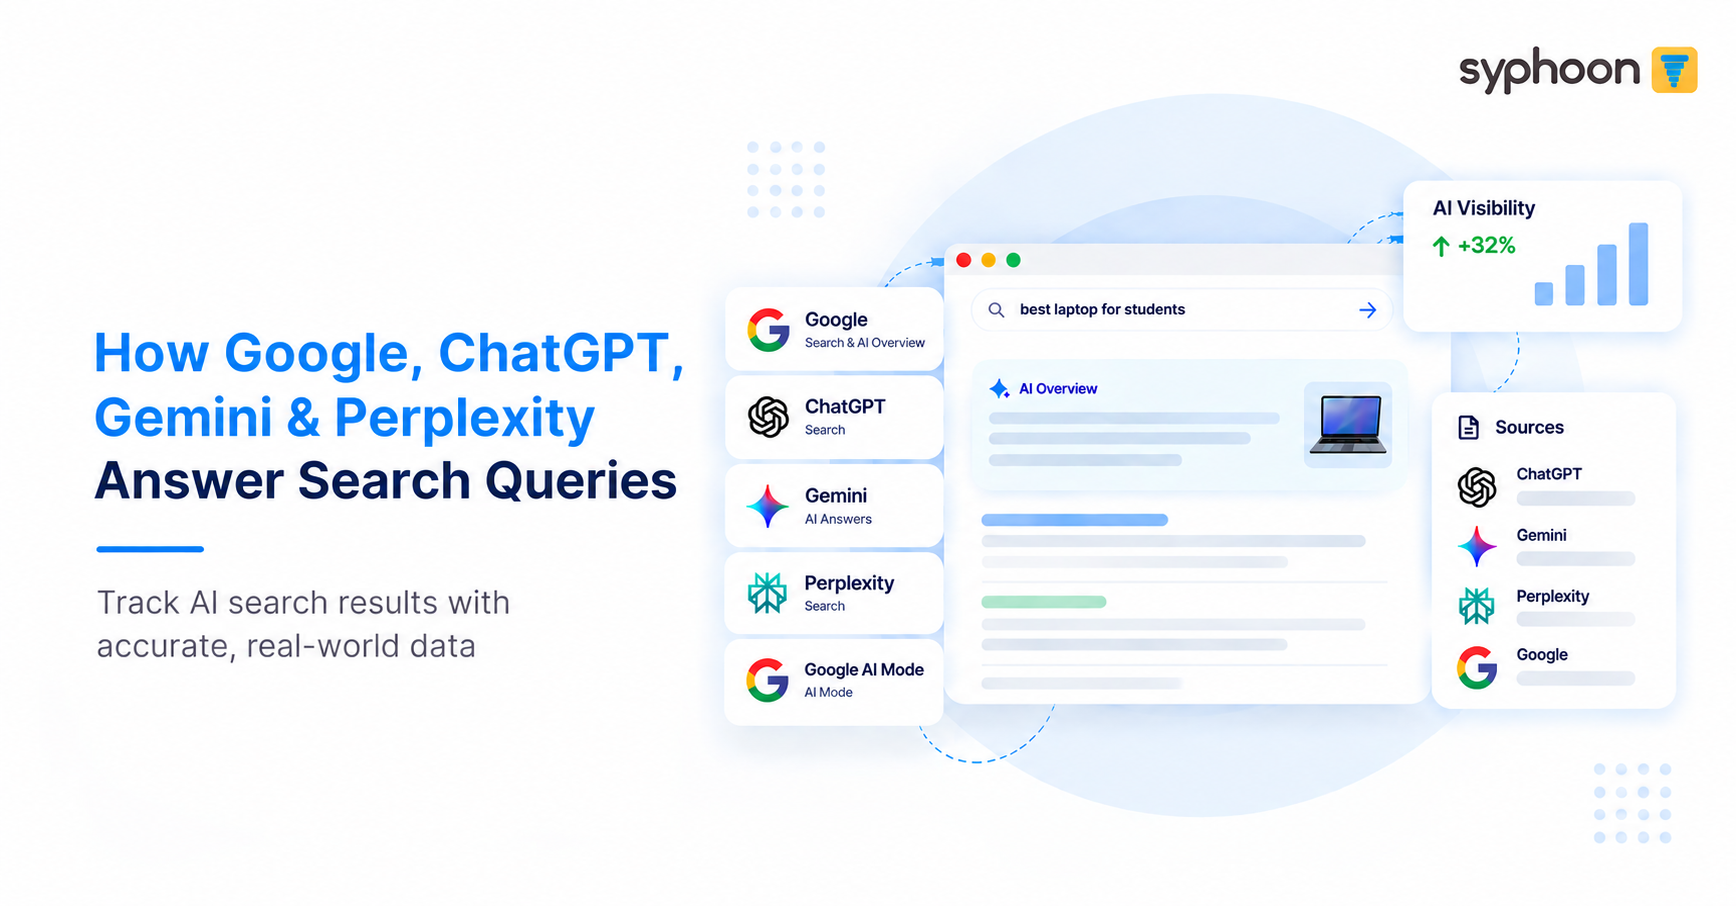
Syphoon LLM Scraper: How Google, ChatGPT, Gemini & Perplexity Answer Search Queries
Track how Google, ChatGPT, Gemini, and Perplexity actually answer search queries, including AI Overview and AI Mode. Six dedicated endpoints, one clean data layer.